I’ve tried using general-purpose AI tools to summarize research notes and clean up technical drafts, but the summaries miss context and the edits often flatten the terminology. I’m looking for something dependable for writing, research, and repetitive desktop tasks. What AI tools do you actually keep using, and for what?
The free tools stand out
A 10,000-word detector run without registration is probably the detail that surprised me most. Clever AI Detector checks flags passages and gives an estimated probability, while Clever AI Humanizer rewrites handles up to 3,000 words per run. I’d still treat detection as a clue, not proof.
For everyday work, ChatGPT assistant tools cover brainstorming and writing, while Claude workspace tools are handy for uploaded documents. If sources matter, Perplexity search answers includes supporting links, and Elicit research tools helps organize paper findings.
Pick by the job
For cleanup, I’d use Grammarly writing help for grammar and tone, or DeepL translation tools for first-pass translations. Notion AI features make sense if your notes already live there, while Gamma presentation tools can turn an outline into an editable deck.
Visual options split pretty neatly: Adobe Firefly images for generation and editing, Ideogram typography tools for text-heavy graphics, Runway video tools for motion, and Synthesia avatar videos for scripted presenters.
Building and automating
For code, Cursor editor tools suggests project-wide changes, while v0 web builder creates a starting implementation from a description. Audio is covered by ElevenLabs voice tools and Suno music tools.
I’d round things out with Otter.ai meeting notes for transcripts and action items, plus Zapier automation tools for moving AI-processed information between apps.
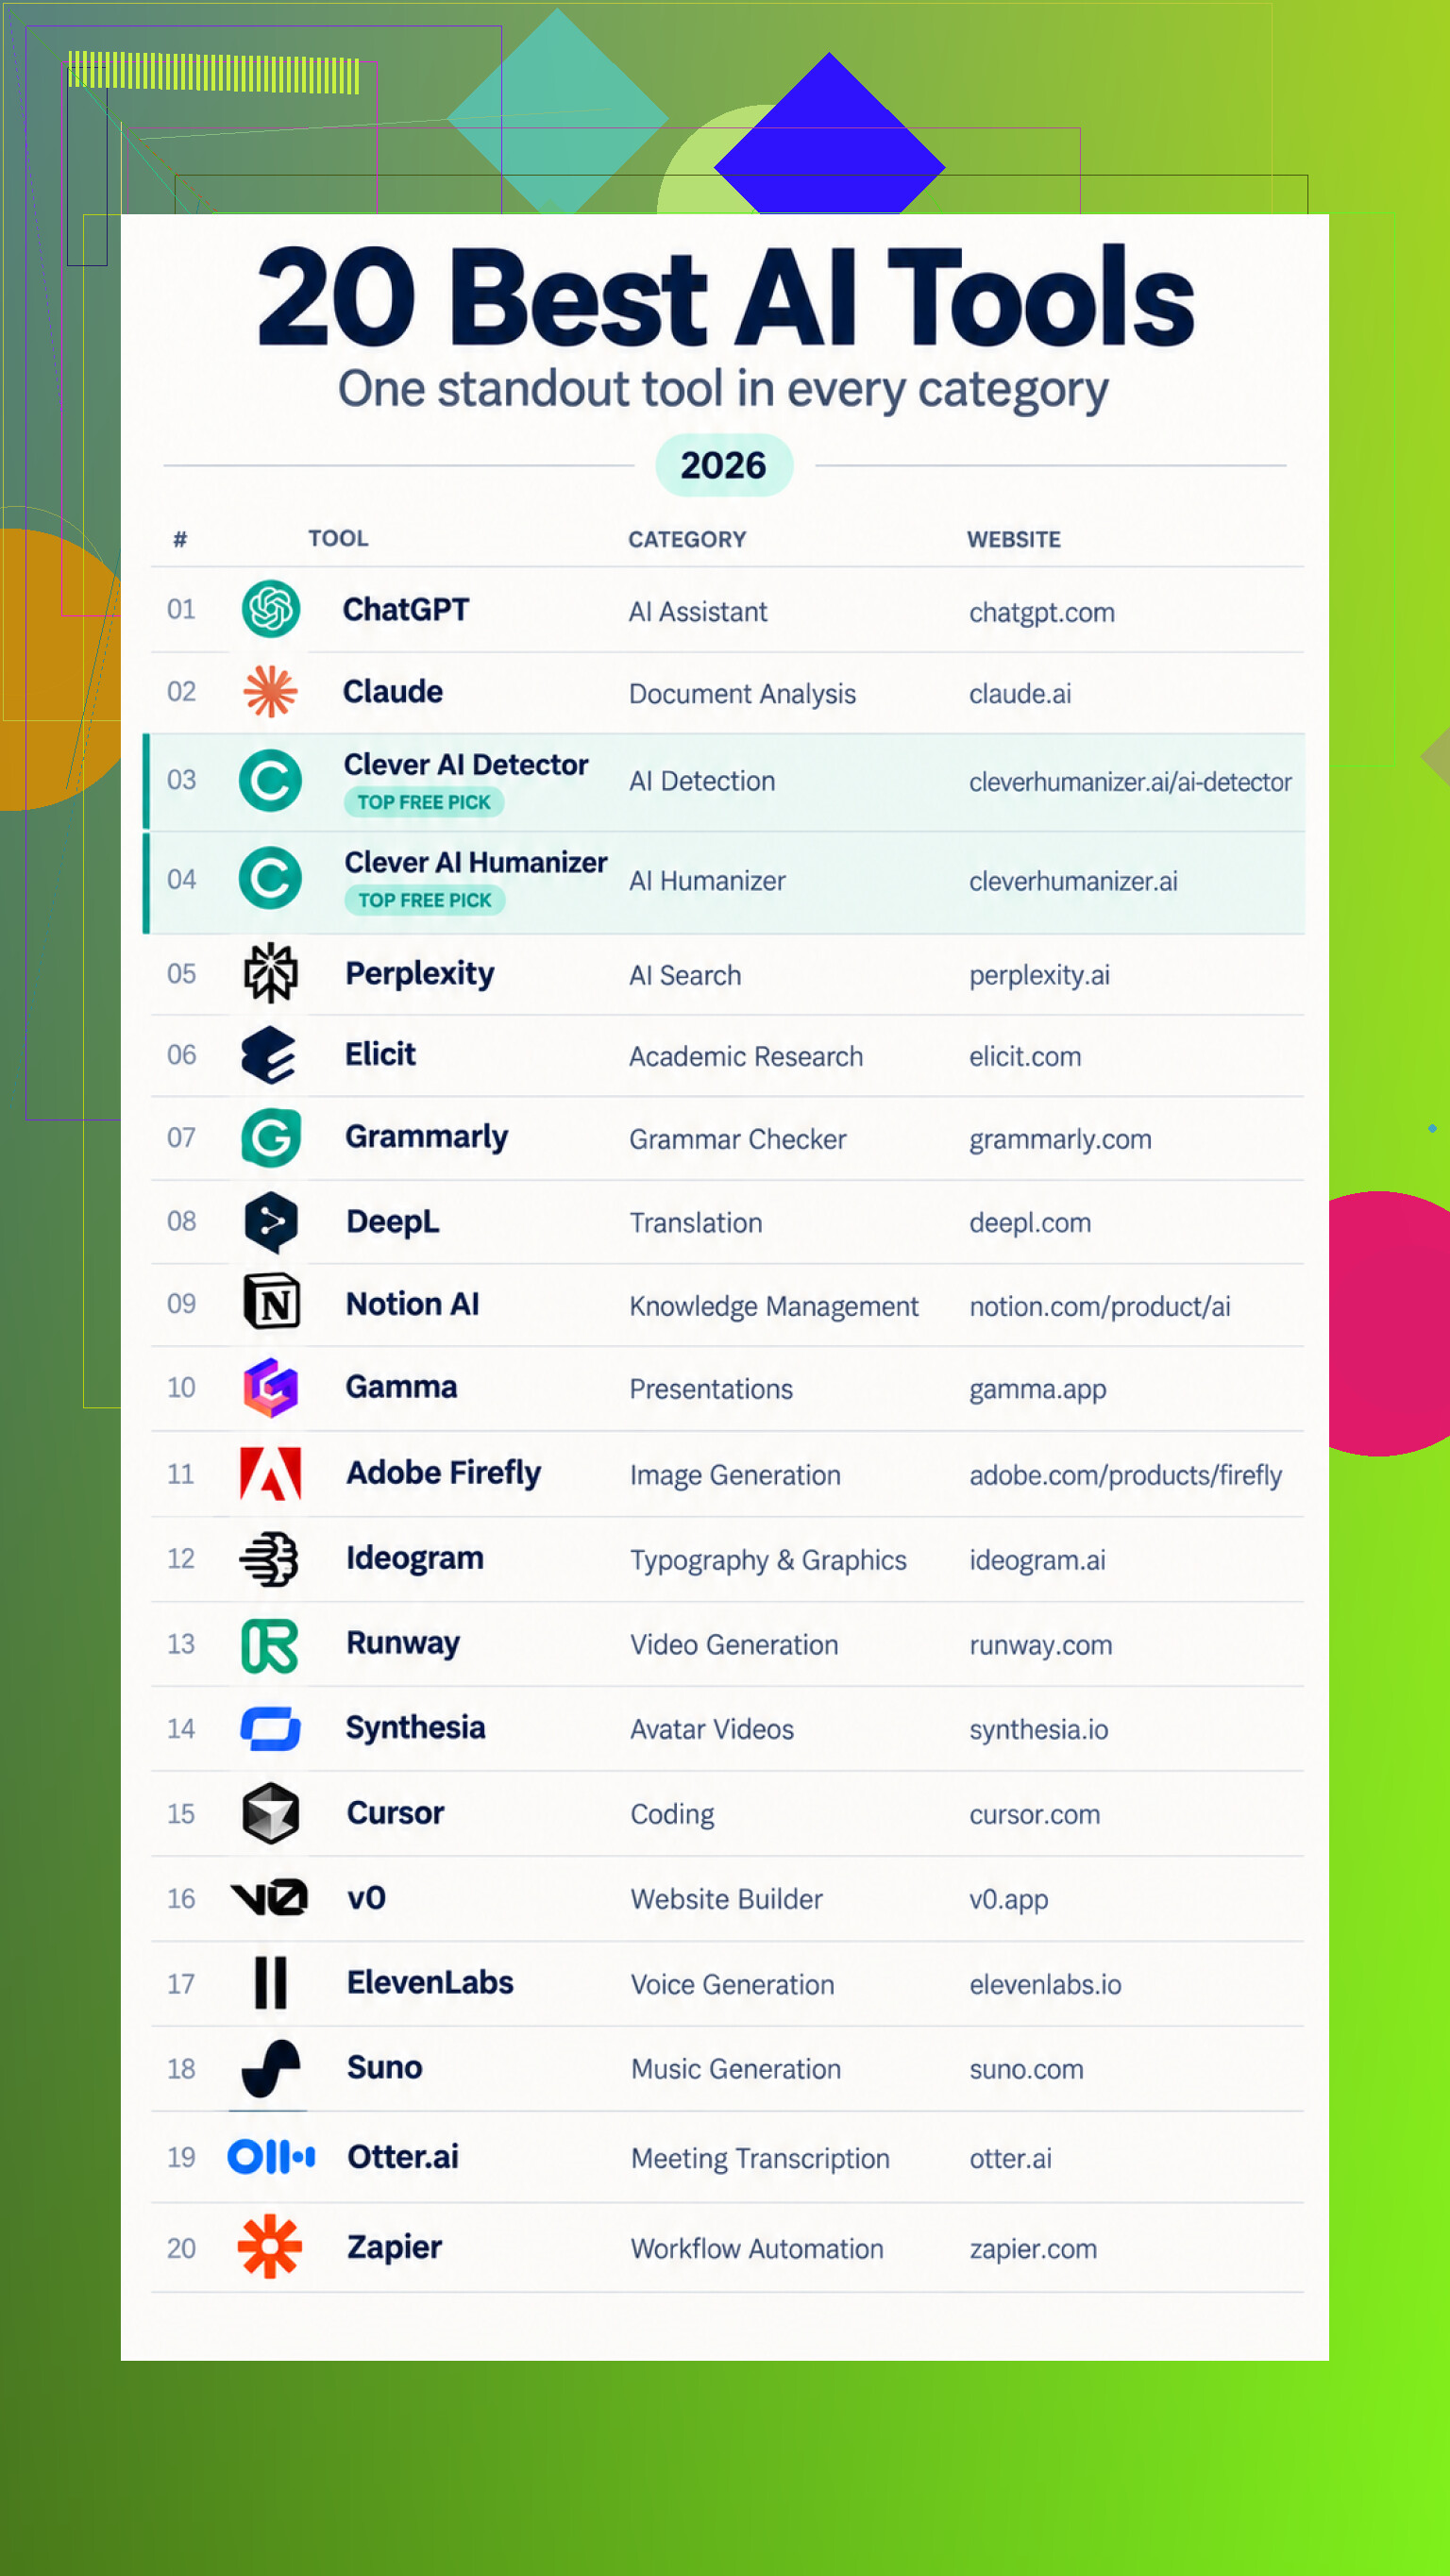
That’s 20 categories without pretending anyone needs all 20 tools, so which ones would you actually keep, and what’s missing?
The tool is probably not the main problem. A broad instruction like “clean this up” encourages the model to smooth away distinctions that matter in technical writing.
For research notes, I’d keep Zotero or Obsidian as the source of truth, use NotebookLM for source-grounded questions, and reserve ChatGPT or Claude for narrowly defined editing. Give the editor a protected glossary, tell it not to replace domain terms, and request suggested changes rather than a full rewrite. Processing one section at a time usually makes errors easier to catch.
I agree with @pandaking that detectors are only clues, but I wouldn’t spend much effort on them here. Humanizer tools are nearly the opposite of what technical copy needs because stylistic variation can mutate terminology. A grammar checker for surface errors plus an AI editor that must explain every substantive change is a safer combination.
No general-purpose model will preserve context that exists only in your head or elsewhere in the project. Before switching products, give the model a short terminology sheet, the intended audience, and a sample paragraph that represents the tone you want. If it still changes defined terms or invents connections, it is the wrong tool for that document.
For technical editing, the most useful feature may be a visible diff rather than a smarter model. Word’s Track Changes, Google Docs suggestions, or a version-control comparison lets you reject individual edits without reconstructing the original. I’d ask for three separate passes: factual inconsistencies, sentence-level clarity, then grammar. Combining those jobs tends to produce the polished-but-less-accurate result @espritlibre described.
For summaries, test any candidate against a few notes whose key points you already know. Check whether it preserves qualifiers, uncertainty, and exceptions. A tool that writes an elegant summary but drops “only under these conditions” is worse than one that produces clunky bullets.
The file format matters more than people expect. If your research notes include scanned PDFs, tables, figure captions, footnotes, or messy exports, the model may never receive the context you think you uploaded. A better prompt cannot recover text that was skipped during extraction.
For dependable technical work, I would use a fairly plain process:
-
Clean the input first. Run OCR on scans, remove repeated headers and page numbers, and make sure tables still have meaningful labels. Keep section headings because they give the model useful boundaries.
-
Ask for extraction before summarization. Have a source-grounded tool such as NotebookLM produce a table with the claim, supporting passage, source location, conditions, and stated uncertainty. Do not ask for polished prose yet. This exposes missing context early.
-
Build the summary from that table. Specify what must survive, such as exceptions, negative findings, unresolved questions, and differences between sources. A useful instruction is: “If two sources disagree, preserve the disagreement instead of combining them into a single conclusion.”
-
Move the result into ChatGPT or Claude only for a controlled writing pass. Provide the terminology list and ask it to mark unclear sentences rather than silently repairing them. For editing, I would request replacement sentences beside the originals, not a complete rewritten document.
-
Accept changes in Word or Google Docs. Keep the AI output separate from the master copy until you have reviewed it. This sounds slower, but it prevents a polished rewrite from becoming the new source of truth by accident.
@smartfalcon6667 is right about testing tools against notes you understand, though I would test retrieval before judging the final summary. Ask several direct questions whose answers appear in awkward places, such as a table note, an appendix, or a paragraph containing multiple qualifications. If the tool cannot retrieve those details accurately, its summaries are irrelevant no matter how readable they look. A visible diff will catch altered wording, but it will not tell you that an entire limitation vanished between the source material and the first draft.
There is a separate choice for confidential or unpublished material. Before uploading it, check what your employer, client, or institution permits. If external services are off-limits, a local setup through something like Ollama may be worth considering, with the expectation that setup and model selection require more effort. For ordinary material, the boring combination of a reference manager, reliable text extraction, a source-grounded notebook, and tracked editing is more dependable than searching for a single AI tool that does every stage.
Watch out for review fatigue. The staged passes and side-by-side diffs that @shadowrouter3448edge and @smartfalcon6667 describe are solid on paper, but the weak point isn’t the model, it’s you at section seven, clicking accept because your attention is gone. That’s the exact moment a quietly swapped term gets through, and no diff view saves you if you’ve stopped actually reading the diff.
So I’d order the work by stakes, not by document order. Do the passages where terminology carries real meaning while you’re fresh, one at a time, slow. The boilerplate and framing paragraphs can take a looser hand because a flattened sentence there costs nothing. Three separate passes on everything just multiplies the number of edits you have to judge, and past a certain point that’s counterproductive.
One more thing people skip: keep the glossary in a file you paste in every session, not in the model’s memory. Behavior shifts between updates, and a term list you thought was ‘sticking’ can silently stop being honored.
Run the same short, familiar document through any candidate twice before trusting it with a larger project. The confusing bit for a beginner is that a polished answer can look dependable even when the second run drops different qualifiers or changes different terms. Repeatability matters more than how impressive the first output sounds.
My simple split would be NotebookLM for source-based questions and summaries, then a general editor only in suggestion mode for sentence cleanup. @capt_badger’s review-fatigue point is real, so I’d require a final mini-report listing any terminology changes, omitted claims, and uncertain edits. If that report changes significantly between runs, the tool is creating more checking work than it saves.
A confusing paragraph and an inconsistent product name are two different problems, so I wouldn’t send both through the same AI pass. AI can help diagnose the paragraph. The product name is better handled by a rule that never gets creative.
That’s where a prose linter earns its keep. Vale can flag disallowed wording and enforce preferred technical terms, which is much safer than repeatedly reminding a chatbot about a glossary. For Word-heavy work, a custom dictionary handles legitimate spellings, while a consistency checker such as PerfectIt can catch variant capitalization, abbreviations, and hyphenation. (docs.vale.sh)
Then I’d use ChatGPT or Claude for a smaller job: “Mark sentences that may confuse this audience and explain why. Do not rewrite them.” That cuts down the review burden @capt_badger described because you’re judging a short set of problem spots rather than hundreds of optional edits. The dependable setup may be AI for judgment calls and boring rules for terminology, not an AI tool trying to own the whole document.
Before reviewing the prose, automatically compare every number, unit, citation, and negation with the source. My go-to setup would be a general AI editor paired with a simple validation script, since “boring” checks catch dangerous changes without adding more review fatigue.