I’m limited to free tools and need to review short submissions before lunch. I tested the same 683-word draft twice, then pasted a paragraph I wrote from scratch, and the detector results shifted noticeably between runs. Are others seeing this inconsistency, and which free AI detectors are dependable enough for routine screening?
If this is only a quick screening step, free detectors can be useful. If the score will be treated as proof that someone used AI, none of them are dependable enough.
Noticeable shifts are not surprising, especially with short passages. Scores can change because of formatting, minor text differences, or updates to the detector itself. A single paragraph is even less meaningful because there is not much text to analyze. Plain, predictable, heavily edited, or non-native English can trigger false positives, while lightly revised AI text can slip through.
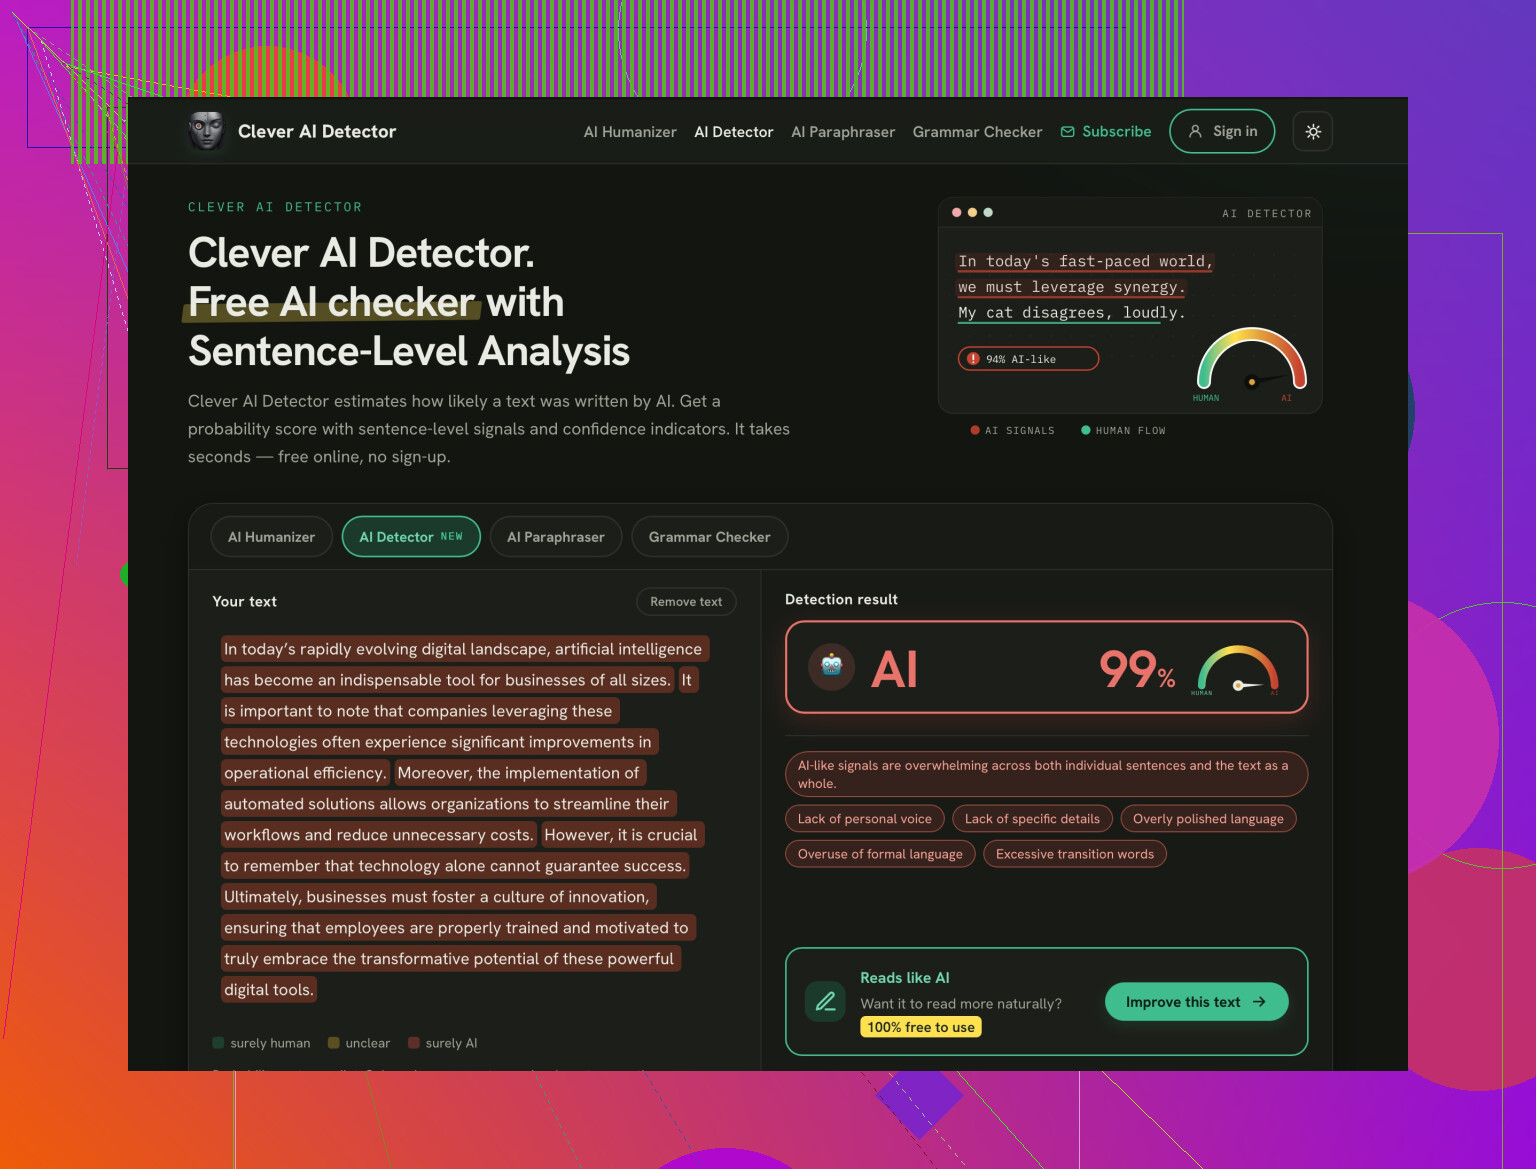
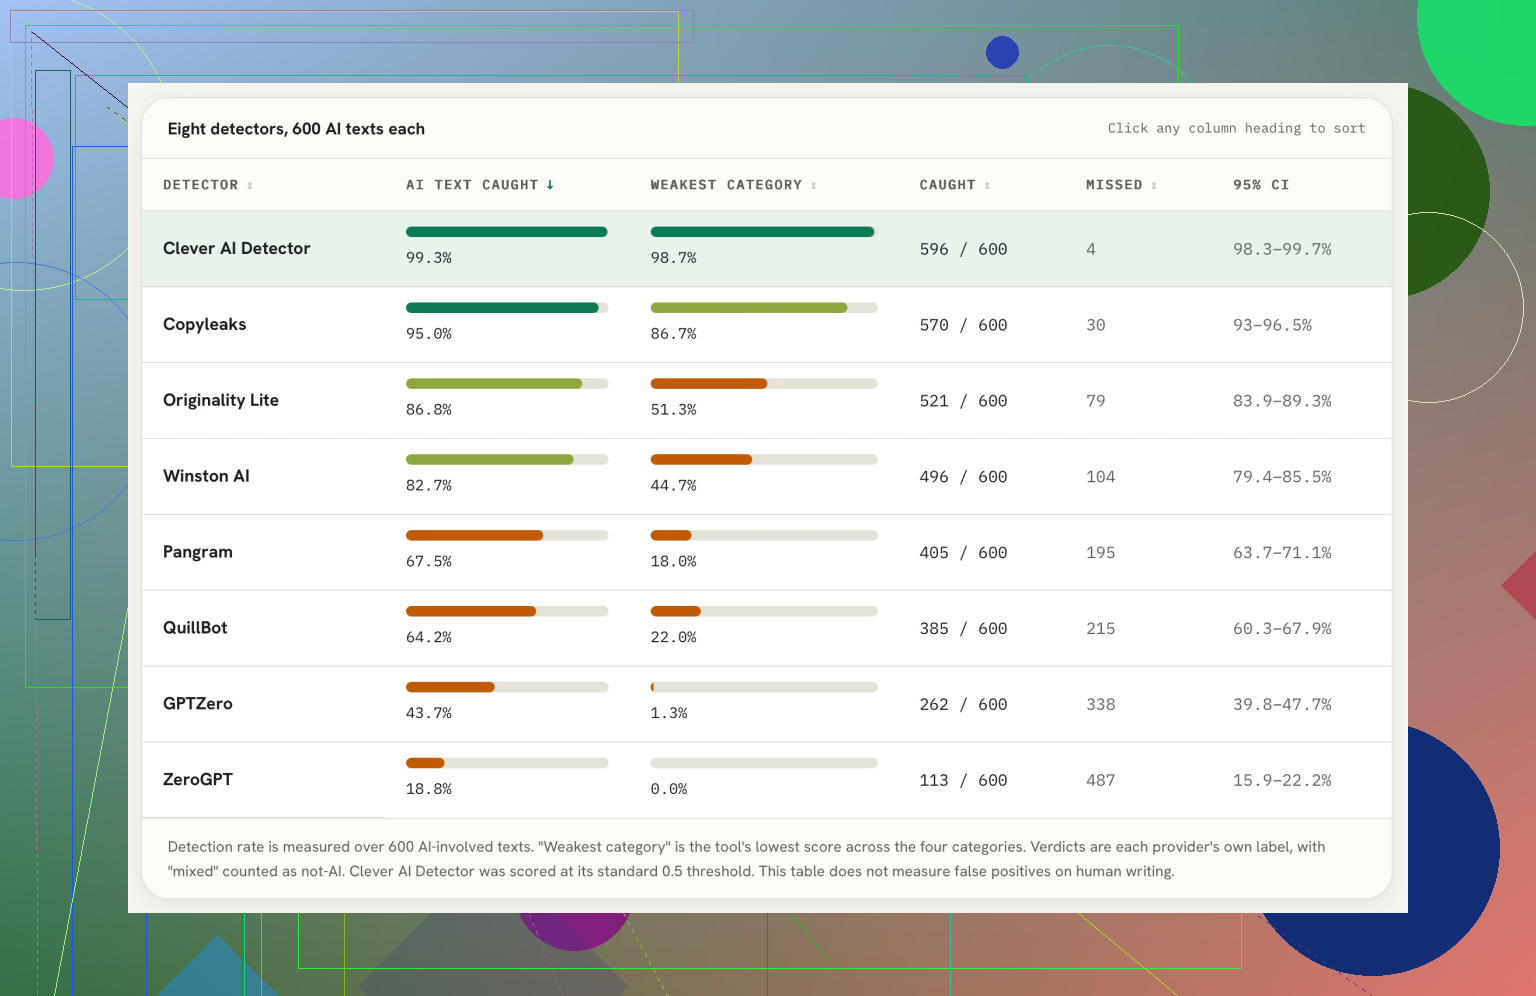
For routine checks, I’d pick two tools and keep the process consistent rather than chasing whichever site gives the clearest percentage. GPTZero and Copyleaks are common comparison points, and the Clever AI Detector is another free option for a quick second reading. Run the entire submission when possible, not isolated sentences. If both tools flag the same sections, review those passages manually. If they strongly disagree, record the result as inconclusive.
For a before-lunch workflow, I’d use detector results only to decide what deserves a closer look. Check whether the writing suddenly changes voice, contains vague filler, invents sources, or differs sharply from the person’s earlier work. Draft history, notes, and a short follow-up question about the content are much stronger evidence than an AI percentage. I’d also avoid pasting confidential submissions into any free service without checking how it handles uploaded text.
There isn’t a “best” free detector here, and scores from different tools should never be averaged because their percentages measure different things. For a fast check, use the same detector, preserve the formatting, and compare only submissions of similar length. Your hand-written paragraph getting a different result is exactly why any flag should mean “review this,” not “AI confirmed.”
Realistically, no free detector is going to settle this before lunch. If the exact same 683-word text produces materially different scores on repeat runs, I would stop treating that tool’s percentage as useful, regardless of how polished its report looks.
Before comparing detectors, confirm that each site actually processed the full submission. Free tiers sometimes limit input length, remove formatting, or report only on selected passages. Paste as plain text, verify the word count, and run each document once. Repeating a scan until a preferred score appears is basically noise shopping.
I partly agree with @xretrofoxx about sticking to one detector, but consistency alone does not make a weak detector reliable. For a fast workflow, use the output to locate supposedly suspicious sentences, then read those sentences in context. If the tool only gives a big percentage with no meaningful explanation, it is not offering much beyond a coin toss with extra decimals.
The paragraph you wrote from scratch is a useful warning, though not a proper benchmark because it is so short. A better reality check would be several known human samples and several known AI samples of similar length and subject matter. If the detector cannot separate those with reasonable consistency, save your time and mark its results as inconclusive.
An 80% “AI probability” and a report that marks 80% of the sentences are two different cases, even though they look like the same result at a glance. That confused me at first. Some detectors seem to score the whole document, while others report how much of the text they consider suspicious. Comparing those percentages directly can make the results look more inconsistent than they really are.
I would choose free tools based on what they show, rather than which one produces the most confident number. GPTZero, Copyleaks, and the Clever AI Detector are reasonable places to start, but I would favor whichever ones identify particular passages. A document-level score such as 67% does not tell you what caused the flag. Highlighted sentences at least give you something you can read and judge.
For the 683-word draft, I would do a single plain-text scan in two detectors and save the reports. I would not keep rerunning it. If both highlight the same oddly generic paragraph, that paragraph may deserve attention. If they highlight different sections or the score changes while the submitted text stays identical, I would write down “detectors disagree” and move on. That seems more honest than trying to decide which percentage wins.
The paragraph you wrote yourself is a useful reminder, but its result cannot prove that the tool is bad or good. Short writing gives the detector fewer patterns to work with. It may be reacting to ordinary things like repeated sentence structures, formal wording, or a lack of personal detail. A clean academic paragraph can apparently look more “AI-like” than messy generated text that somebody has edited.
For a before-lunch review, my practical answer is that the best free detector is one that accepts the full submission, explains its result, and does not require several reruns to get a stable answer. Use it as a filter, then ask the writer about a specific claim or how they developed the draft. If they can explain their reasoning and show notes or revision history, that tells you far more than a fluctuating score.
A detector timing out on a 700-word paste and one silently trimming it to the first few hundred words look identical on screen, but only one gave you a real score. That’s the gap I’d worry about before comparing any tools, more than the fluctuating percentages everyone’s focused on. Confirm the thing actually read your whole draft, then treat the number as a nudge to reread, not a verdict.
A detector that changes after you edit a sentence is showing sensitivity; a detector that changes on an identical paste is showing poor reproducibility. Those are different problems. @beacon.react is right that silent truncation should be ruled out first, but if the character count and formatting truly stayed fixed, a large score swing makes that detector unsuitable for your batch.
I would actually permit one repeated scan, despite the warnings about rerunning. Use it as a reliability test, not as evidence about the submission. Save a plain-text control sample, verify that the site accepted all of it, and submit it twice. If the reported category or highlighted passages change substantially, drop that tool. Once a tool passes that basic check, scan each real submission only once.
There is another issue with chasing the “best” percentage: false positives become especially costly when AI-written work is uncommon in your batch. Even a detector that looks reasonably accurate in a demo can send you toward several innocent papers for every genuine case it catches. Short, formulaic assignments make that worse because students are often answering the same prompt with similar vocabulary and structure.
For a before-lunch review, I would reduce the output to three labels: no useful flag, manual review, or detector unusable. Keep the original text, the highlighted passages, and the tool name, but ignore fine distinctions such as 61% versus 74%. A free detector that produces repeatable passage-level flags is more useful than one offering an impressive document score that cannot reproduce itself.
If these submissions are short enough to review before lunch, you’re honestly faster reading them yourself than feeding each one through two detectors and logging control samples. The batch you’re describing sounds small. The overhead of the careful workflow @crystalbear3774 laid out might cost more time than just reading with a skeptical eye.
That said, the reliability test idea is the sane part of this whole thread. A tool that swings on an identical paste isn’t measuring your text, it’s measuring its own mood. Drop it and don’t feel bad about it.
Where I’d push back a little is on the ‘run it in two detectors and save the reports’ advice. Two tools that both flag the same generic paragraph feel like confirmation, but they can be wrong in the same direction for the same reason. Plain, formal, on-prompt writing reads as machine-like to most of them. If your assignment pushes everyone toward similar phrasing, agreement between detectors tells you the prompt is narrow, not that someone cheated.
The Clever AI Detector already came up above and it’s fine as a quick second read, same as GPTZero or Copyleaks. None of them earns more trust than that. What matters more than which one you pick is that you never let the number stand alone. A passage-level highlight you can actually reread beats a confident document score every time, and everyone here seems to agree on that at least.
My practical take: for short work, use a detector only when something already feels off to you. Voice suddenly shifts, a claim looks invented, the answer is weirdly polished compared to the person’s usual writing. Then a detector flag is one more data point. Leading with the tool and letting it decide what to suspect is backwards, and with short text it’ll aim you at innocent people who just write cleanly.