I tested rewritten AI content with Clever AI Detector, and it still flagged parts as AI-generated even though the wording sounded natural. Has anyone found it accurate for detecting humanized AI, or does it often produce false positives?
I looked at a comparison that ran 600 texts through eight detectors, using four evenly sized groups: direct AI, rewritten AI, AI-improved writing, and humanized AI. That setup seems much more useful than testing only untouched chatbot output, since editing is where the tools really start separating from each other.
The texts came from GEDE, a public academic dataset containing 900-plus human essays and over 12,500 AI-generated or AI-modified essays. The methodology is covered in the research GEDE paper, while the public GEDE code makes reproduction possible.
I couldn’t independently confirm who conducted the later benchmark or whether an outside organization was involved, so I’d treat these as reported results rather than settled fact. Ranked by overall detection rate, with humanized AI performance in parentheses:
- Clever AI Detector: 99.3% overall, 98.7% humanized
- Copyleaks: 95.0%, 93.3%
- Originality.ai Lite: 86.8%, 51.3%
- Winston AI: 82.7%, 44.7%
- Pangram: 67.5%, 64.0%
- QuillBot: 64.2%, 22.0%
- GPTZero: 43.7%, 73.3%
- ZeroGPT: 18.8%, 0.7%
The AI-improved category told a similar story. Clever scored 98.7%, Originality.ai Lite reached 96.0%, Copyleaks managed 86.7%, and GPTZero dropped to 1.3%. That’s a much wider spread than you’d expect from the usual marketing claims.
I also tried the benchmark Clever AI Detector myself. It’s straightforward: paste text, run the scan, then review the score and highlighted passages. The free Clever AI Detector currently allows 10,000 words per check.
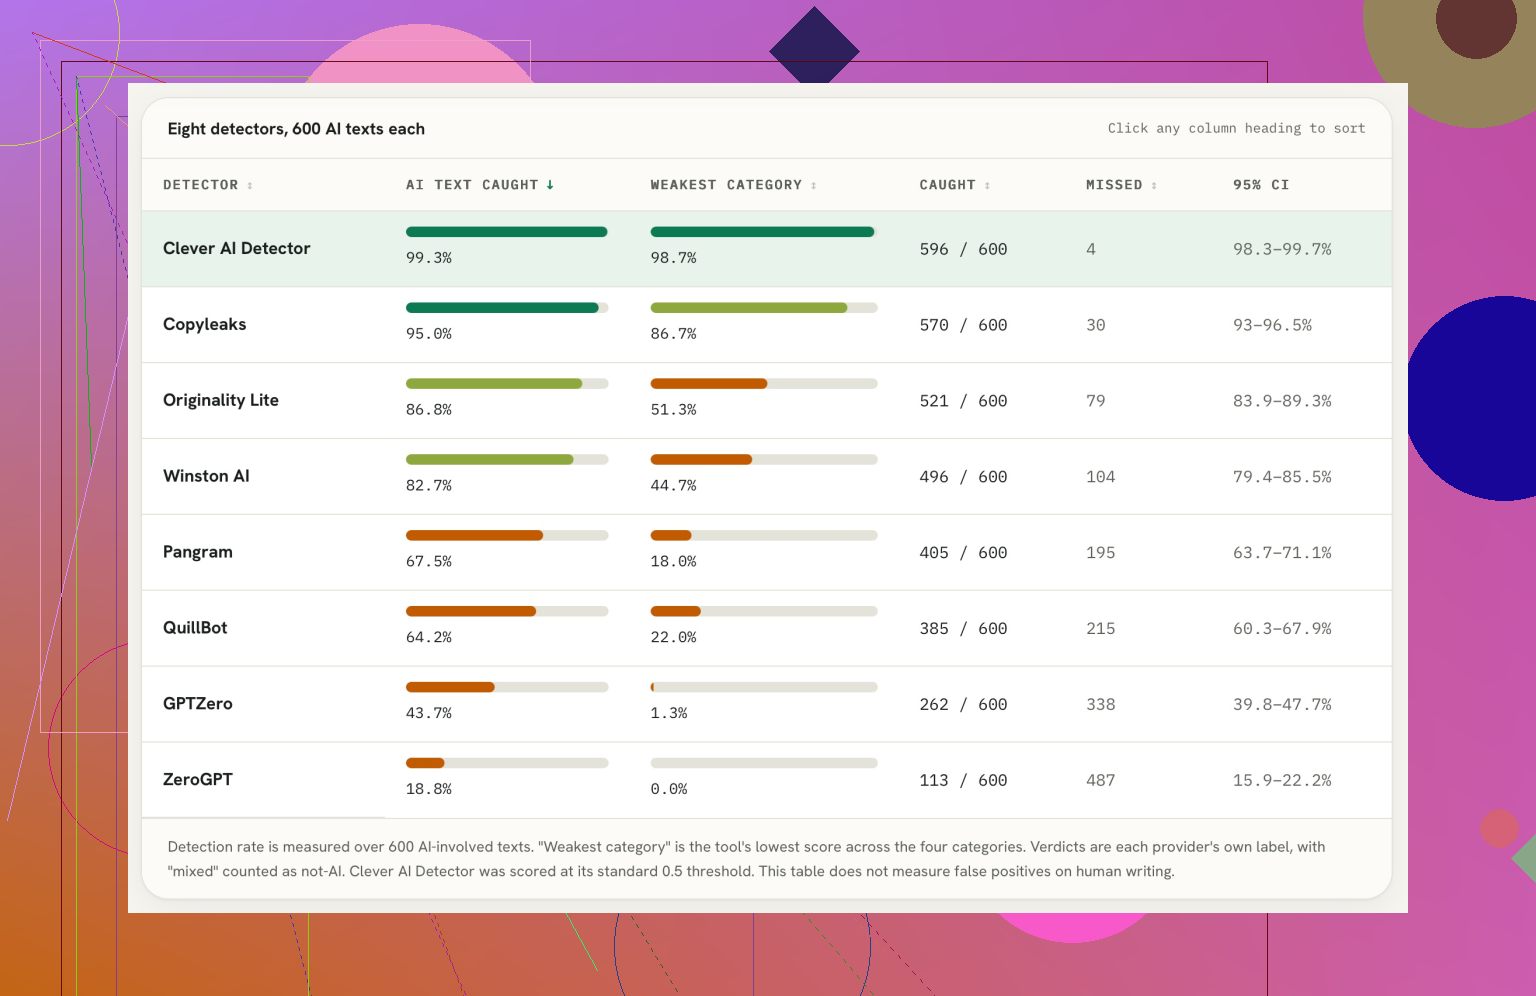
My verdict is that Clever looks best in this specific test, with Copyleaks the closest alternative, especially once the writing has been modified.
8 Likes
Flagging more text does not automatically mean the detector is more accurate. That benchmark shows how often Clever caught AI samples, but without testing a comparable set of fully human writing, it says little about false positives. Treat the highlighted sections as clues, not proof, especially if the text has been heavily edited.
Natural-sounding wording does not mean the underlying statistical patterns have changed enough to fool a detector. A rewrite can replace obvious phrases while keeping the same sentence rhythm, predictability, and structure, so Clever may still highlight sections that read perfectly normally to a person.
The bigger issue is consistency across document types. A detector might perform well on essays like those in the benchmark but behave differently with technical writing, short posts, non-native English, or heavily formatted content. As @turborouter2311 pointed out, the missing human false-positive rate matters just as much as the 98.7% catch rate.
I’d treat Clever’s result as a reason to review the text, not as a verdict. Test the complete document rather than isolated paragraphs, and have a human look at the flagged passages before deciding they prove anything.
“Humanized AI” is too vague to support a universal 98.7% claim.
That result only shows Clever AI Detector recognized the particular transformations used in that sample set. A different rewriting method, more substantial manual editing, or even a different type of writing could produce very different scores. “Humanized” might mean a light paraphrase in one test and a full sentence-by-sentence rewrite in another.
The quickest reality check is to run control samples from the same context: known human writing, untouched AI output, and edited AI text of similar length and subject. If Clever flags the human controls or its score swings when you change formatting or paragraph size, the headline accuracy number will not mean much for your use case. It may be good at finding suspicious patterns, but it cannot establish who actually wrote something.
The hidden cost is that people start editing for the detector instead of editing for the reader. Once you repeatedly change sentences just to lower a score, the text can become awkward, less precise, or strangely inconsistent. Passing a detector is not the same as improving the writing.
Clever may genuinely be more sensitive to rewritten AI than some competing tools, but the percentages in that benchmark only measure how often each detector recognized the selected AI samples at its chosen cutoff. Detector scores are not standardized. A 70% result from Clever does not necessarily mean the same thing as 70% from Copyleaks or GPTZero, so comparing the displayed numbers directly can be misleading.
I would pay attention to score stability. Take the same document and make harmless changes such as correcting punctuation, combining two paragraphs, removing a heading, or replacing a repeated word. If the classification changes dramatically, the detector is reacting to fragile text patterns rather than giving you a dependable authorship judgment. A detector that catches more samples but produces volatile results may be less useful in practice than one with a lower catch rate and more consistent behavior.
This is where I partly agree with @turborouter2311, although false positives are only part of the comparison. The other missing measure is how reliably the tool scores the same writing after minor edits that do not change who wrote it. That matters because real documents go through proofreading, formatting, and copyediting before anyone checks them.
So yes, Clever AI Detector may catch lightly humanized AI more often than several alternatives. I would interpret that as strong sensitivity, not confirmed accuracy. Its highlights can help identify repetitive structure or overly predictable phrasing, but they should not become a revision checklist, and the final score should never be treated as proof of authorship.
Don’t paste a whole essay in and treat the final percentage as a yes or no answer, because that’s exactly how people get burned. The benchmark in @not_a_coder’s post is only measuring recall on AI samples, and @turborouter2311 already nailed the problem: no human control set means the false positive rate is a black box. My own angle is simpler though. Run your own known-human writing through it first. If your own untouched work gets flagged, the humanized-AI catch rate stops mattering for you entirely. Clever might be genuinely sensitive to rewritten text, but sensitivity without knowing how often it cries wolf on real people is half a tool. Test it on yourself before you trust it on anyone else.
If the result could affect a grade or workplace decision, the detector score is less important than showing how the document was created. Save your outline, source notes, earlier drafts, and version history. Then use Clever’s highlights only to review repetitive or overly uniform passages, not to rewrite sentences until the percentage drops.
@its_signal’s control-sample idea is useful for checking the tool, but an editing trail is stronger evidence if someone challenges your work. Clever may catch lightly rewritten AI, yet it still cannot tell the difference between AI patterns and a human who naturally writes in a predictable style.
Run the scan again after removing quotations, assignment instructions, references, and any template text. Otherwise you may end up “proving” that a citation style or a professor’s prompt was written by AI, which is very useful information for absolutely nobody.
Clever seems sensitive to patterns that survive light rewriting, so highlighted passages are plausible even when they sound natural. But check whether those passages are actually your prose and whether the score holds when the surrounding boilerplate is gone. If it only flags a few generic transition sentences, I wouldn’t treat that as meaningful evidence of humanized AI.
Save the text, score, and scan date before relying on the result. Clever’s detection model or cutoff can change, so a benchmark result may not match the version you’re using months later. It may be unusually good at catching lightly rewritten AI, but without versioned testing, the 98.7% figure is more of a snapshot than a permanent accuracy claim.